
PowerShell can’t convert PDF to Word by itself, but desktop Microsoft Word can, and PowerShell drives Word through COM. Open the PDF in a hidden Word instance and save it as .docx:
$doc = $word.Documents.Open($pdf, $false, $true)
$doc.SaveAs2($docx, 16)
Word rebuilds the PDF as an editable document, and 16 is the .docx format code.
Below you’ll find the full script, a folder version, what Word keeps and loses, and the hidden prompts that can freeze an unattended run. I tested all of it with Word 16 in PowerShell 7.6 and Windows PowerShell 5.1.
What you need to convert PDF to Word with PowerShell
You need Windows with the desktop version of Word installed and activated. Word for the web, a server without Office and Linux won’t work, because the conversion is Word’s own PDF import.
This check tells you if the Word COM class is registered on the machine:
$type = [type]::GetTypeFromProgID('Word.Application')
"Word COM class registered: $($null -ne $type)"
Output:
Word COM class registered: TrueThe same COM object can go the other way too: my guide on converting HTML to PDF in PowerShell uses it to export PDFs.
Convert a single PDF to a Word document
Start with one file. The script opens the PDF read-only, saves a .docx next to it and prints a quick summary:
[string]$pdf  = (Resolve-Path -Path .\PdfDemo\invoice-1042.pdf).Path
[string]$docx = [System.IO.Path]::ChangeExtension($pdf, '.docx')

$word = New-Object -ComObject Word.Application
try {
    $word.Visible       = $false
    $word.DisplayAlerts = 0                            # wdAlertsNone
    $doc = $word.Documents.Open($pdf, $false, $true)   # no Convert File dialog, read-only
    $doc.SaveAs2($docx, 16)                            # wdFormatDocumentDefault = .docx
    '{0} page(s), {1} table(s), {2} words' -f $doc.ComputeStatistics(2), $doc.Tables.Count, $doc.ComputeStatistics(0)
    $doc.Close($false)
}
finally {
    $word.Quit()
    [void][System.Runtime.InteropServices.Marshal]::ReleaseComObject($word)
    [GC]::Collect()
}
"Saved: $(Split-Path -Path $docx -Leaf)"
Output:
1 page(s), 1 table(s), 30 words
Saved: invoice-1042.docx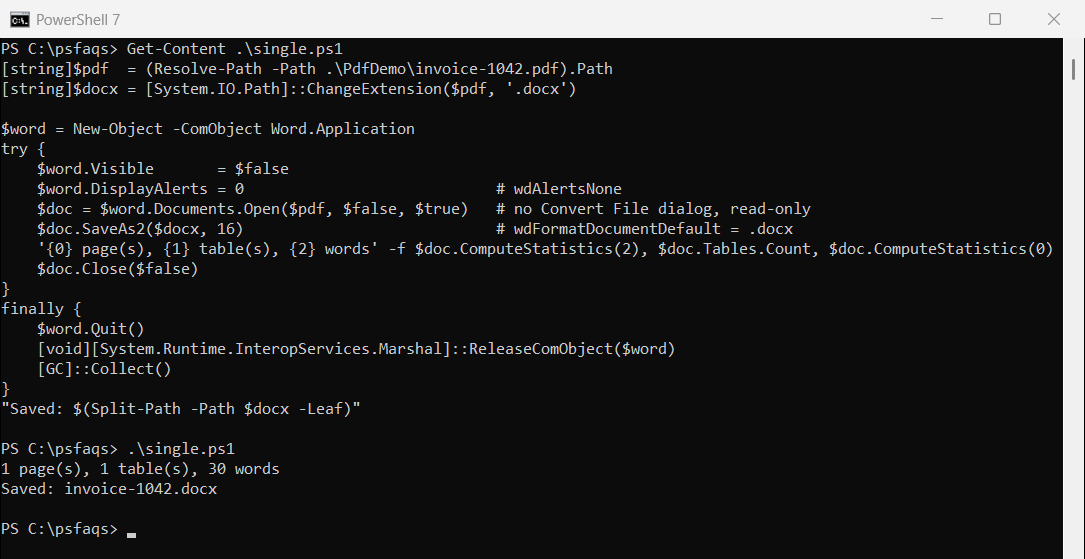
Here’s what the important lines do. The second argument of Documents.Open is ConfirmConversions; $false stops Word from asking which converter to use. The third argument opens the file read-only, so the source PDF is never touched.
SaveAs2 takes the file name and a format code. Use 16 for .docx, 0 for the old .doc format or 6 for RTF. It overwrites an existing file without asking.
The finally block always runs, even after an error. That’s what keeps a failed run from leaving Word in memory. If try, catch and finally are new to you, read that first.
How do I convert all PDFs in a folder to Word?
Start Word once, loop through the PDFs and close it at the end. Starting a new Word for every file is much slower. I wrapped the loop in a function that returns one object per file:
function ConvertFrom-PdfToWord {
    param([Parameter(Mandatory)][string]$Folder)
    $word = New-Object -ComObject Word.Application
    try {
        $word.Visible       = $false
        $word.DisplayAlerts = 0
        foreach ($file in Get-ChildItem -Path $Folder -Filter *.pdf) {
            [string]$pdf  = $file.FullName
            [string]$docx = Join-Path -Path $file.DirectoryName -ChildPath ($file.BaseName + '.docx')
            try {
                $doc = $word.Documents.Open($pdf, $false, $true)
                $doc.SaveAs2($docx, 16)
                [pscustomobject]@{ File = $file.Name; Pages = $doc.ComputeStatistics(2)
                                   Tables = $doc.Tables.Count; Status = 'Converted' }
                $doc.Close($false)
            }
            catch {
                [pscustomobject]@{ File = $file.Name; Pages = 0; Tables = 0; Status = $_.Exception.Message }
            }
        }
    }
    finally {
        $word.Quit()
        [void][System.Runtime.InteropServices.Marshal]::ReleaseComObject($word)
        [GC]::Collect()
    }
}

ConvertFrom-PdfToWord -Folder .\PdfDemo\Inbox | Format-Table -AutoSize
Output:
File                     Pages Tables Status
----                     ----- ------ ------
invoice-1042.pdf             1      1 Converted
onboarding-checklist.pdf     1      0 Converted
policy-remote-work.pdf       2      1 Converted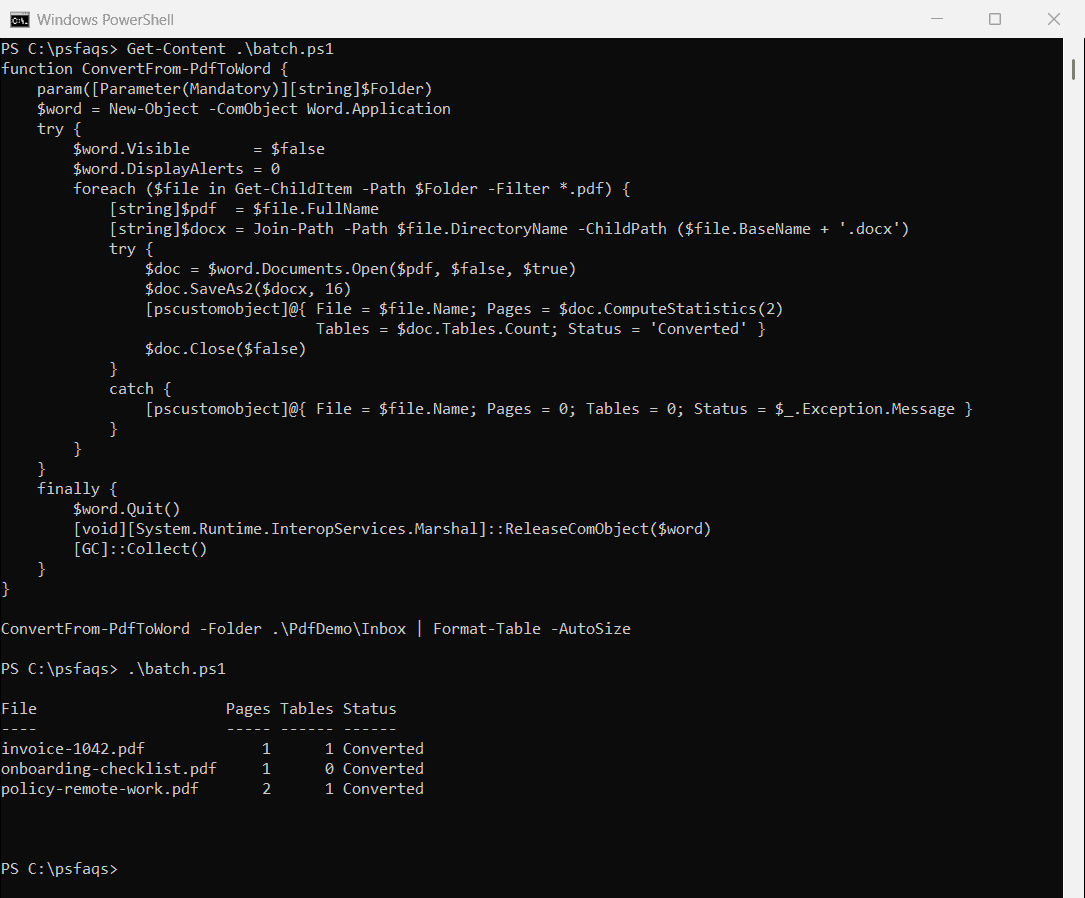
A file that fails gets its error message in the Status column, and the loop moves on to the next PDF. The pattern is the same as any loop through the files in a folder.
Send the results to a CSV or a log if the job runs on a schedule. My notes on writing to a log file in PowerShell show a simple way.
Check what Word kept: headings, lists and tables
Word doesn’t copy a PDF. It rebuilds the document from the page layout, so check the result before you send it on. This script lists the style of every paragraph outside the tables in my two-page policy PDF:
[string]$pdf = (Resolve-Path -Path .\PdfDemo\Inbox\policy-remote-work.pdf).Path
$word = New-Object -ComObject Word.Application
try {
    $word.Visible = $false
    $word.DisplayAlerts = 0
    $doc = $word.Documents.Open($pdf, $false, $true)
    foreach ($para in $doc.Paragraphs) {
        $text = $para.Range.Text.Trim()
        # short lines only (headings, bullets), skipping table cells (12 = wdWithInTable)
        if ($text.Length -in 3..45 -and -not $para.Range.Information(12)) {
            '{0,-10} {1}' -f $para.Style.NameLocal, $text
        }
    }
    "Tables: $($doc.Tables.Count)  Lists: $($doc.Lists.Count)"
    $doc.Close($false)
}
finally {
    $word.Quit()
    [void][System.Runtime.InteropServices.Marshal]::ReleaseComObject($word)
    [GC]::Collect()
}
Output:
Normal     Remote Work Policy 2026
Heading 1  Who it covers
Normal     Full-time staff
Normal     Contractors with a signed agreement
Normal     Interns after 30 days
Heading 1  Office status
Heading 1  Equipment
Normal     Appendix A: contact HR at hr@example.com.
Tables: 1  Lists: 0
The title came through as Normal text, the section headings became Heading 1, and the bullet points turned into plain paragraphs. The table survived with all its rows.
In a separate test, a numbered list did stay a real Word list. Microsoft says the conversion works best with PDFs that are mostly text, and line and page breaks may not match the original.
What happens with scanned PDFs?
A scanned PDF holds pictures of pages, not text. I made one from an image of a receipt and converted it:
[string]$pdf = (Resolve-Path -Path .\PdfDemo\scanned-receipt.pdf).Path
$word = New-Object -ComObject Word.Application
try